The file-receiving application uses Node.js, Express, React, and MySQL for CSV/text intake and operational review. This case includes development-stage improvements to an existing system; it does not imply that the latest processing architecture has already replaced the production workflow.
A shared folder is easy to create and difficult to operate. As volume grows, files arrive late, arrive twice, contain malformed rows, or fail after only part of the work has completed. Without durable state, the team cannot distinguish “not received” from “received but failed.”
Give every file a lifecycle.
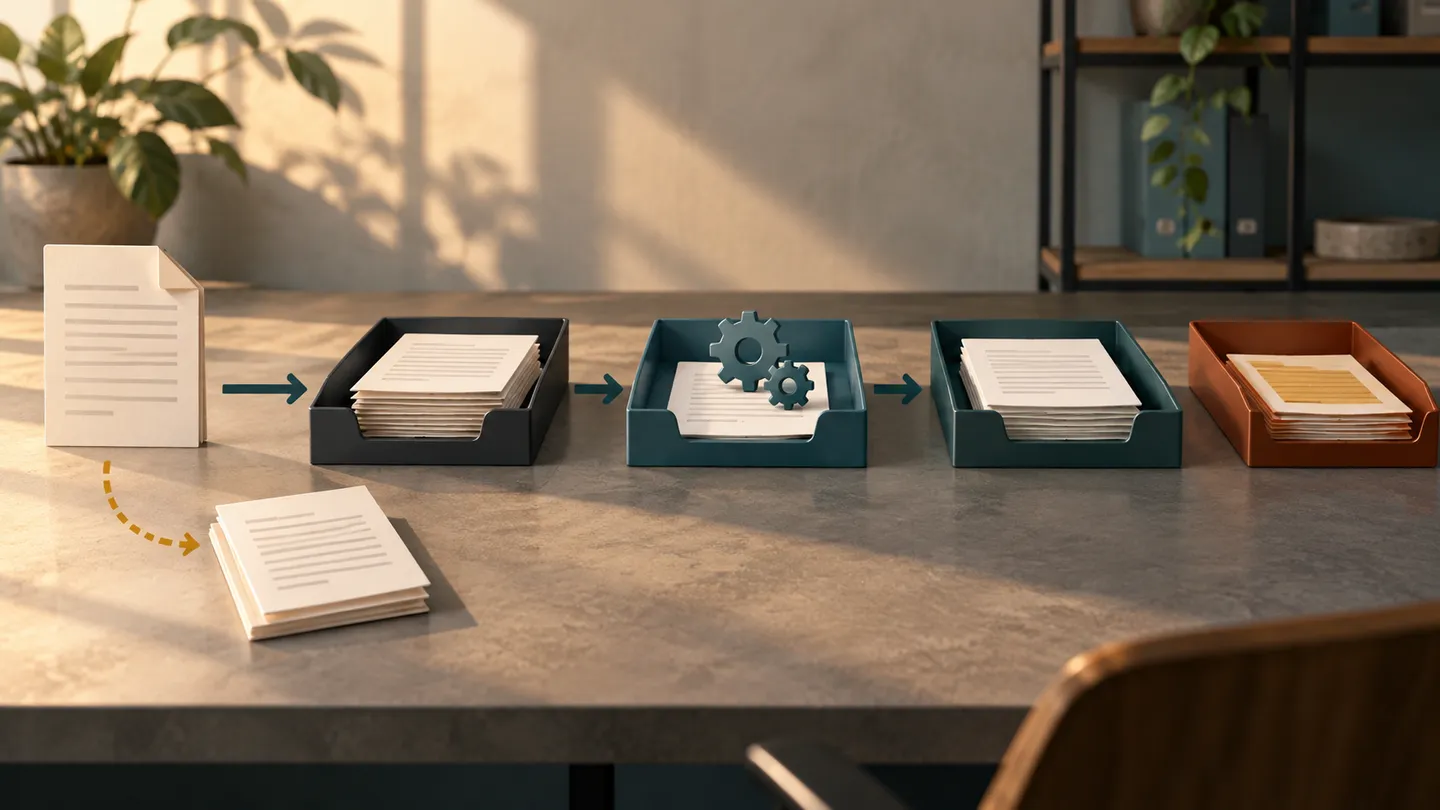
We treated intake as a queue with explicit stages rather than a directory scan. A file enters as received, moves to processing, and ends in a successful or failed state with enough context for an operator to understand what happened.
The original input remains evidence. Processing produces normalized records separately, so a retry does not require editing or renaming the source file.
A file pipeline is an operational application. If people depend on it, it needs state, history, and a recovery path.
Idempotency is the first business rule.
Factories and external partners resend files for good reasons: uncertainty, connection failures, and human caution. The system should make a repeated delivery boring.
We used stable file and record identities to detect duplicates before creating new carton or serial records. A repeat could be acknowledged without duplicating downstream inventory evidence.
The operating surface answered five questions
- What arrived?
- What is waiting?
- What is currently processing?
- What failed, and why?
- Can the failed item be retried safely?
Visibility changes support work.
Once the lifecycle was visible, support conversations became specific. Instead of asking whether “the import ran,” the team could refer to one input, one attempt, and one result. Live status updates reduced the temptation to upload the same file again simply because the first attempt looked quiet.
The same pattern applies far beyond factories. Bank files, marketplace exports, warehouse feeds, and partner CSVs all benefit from preserving inputs and making processing state explicit.
An import needs an operational answer, not just a technical result
When a supplier sends a corrected file or repeats an earlier delivery, the operator needs to know what happened to that submission. A successful upload alone does not establish that all the records were accepted or that they are safe to use.
The queued lifecycle makes the stages understandable: the file was received, processing started, and processing either completed or failed. Retaining the original file gives the investigation a stable reference. It avoids having the evidence change while someone is trying to explain an error.
Stable file and record identities address another practical concern. Retrying an interrupted job should not silently turn the same manufacturing information into a second set of records. Clear duplicate handling and a visible retry path make that distinction part of the operating process.
These are controls around the intake boundary. They do not turn an unreviewed supplier file into trusted data by themselves. The described development work focuses on making acceptance, failure, and follow-up explicit, without presenting newer reengineering as an already completed production deployment.
Reusable pattern: immutable input, explicit lifecycle, stable identity, idempotent processing, and an operator-visible recovery path.